LLM API Price Dataset.
Standard API prices for 10 current Claude, GPT and Gemini models, copied from each vendor's own pricing page and checked every month. You can reuse them under CC BY 4.0.
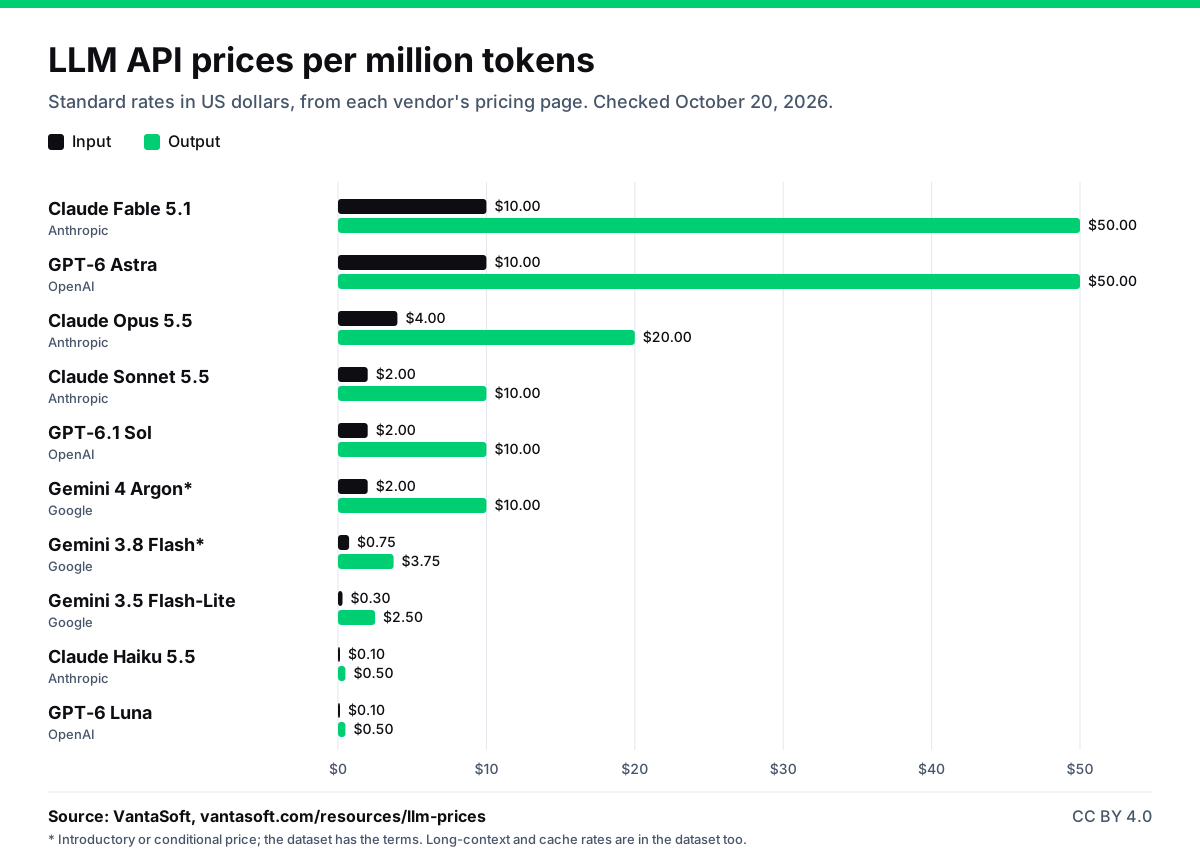
Output prices run from $0.50 per million tokens (Claude Haiku 5.5 and GPT-6 Luna) to $50.00 (Claude Fable 5.1 and GPT-6 Astra), a 100x spread. Prices are in US dollars per million tokens, at standard rates, last checked on October 20, 2026.
Current prices
US dollars per million tokens, standard (non-batch) rates. Long prompts: the rate for the whole request once the prompt passes the length shown.
| Model | Input | Cached input | Output | Cache writes | Long prompts | Source |
|---|---|---|---|---|---|---|
| Claude Fable 5.1 Anthropic | $10.00 | $0.25 | $50.00 | $12.50 (5 min) $20.00 (1 hr) | Same at any length | Anthropic pricing Checked October 20, 2026 |
| Claude Opus 5.5 Anthropic | $4.00 | $0.20 | $20.00 | $5.00 (5 min) $8.00 (1 hr) | Same at any length | Anthropic pricing Checked October 20, 2026 |
| Claude Sonnet 5.5 Anthropic | $2.00 | $0.10 | $10.00 | $2.50 (5 min) $4.00 (1 hr) | Same at any length | Anthropic pricing Checked October 20, 2026 |
| Claude Haiku 5.5 Anthropic | $0.10 | $0.01 | $0.50 | $0.125 (5 min) $0.20 (1 hr) | Over 100K tokens: $0.50 in, $2.50 out | Anthropic pricing Checked October 20, 2026 |
| GPT-6 Astra OpenAI | $10.00 | $1.00 | $50.00 | $12.50 (30 min) $25.00 (12 hr) | Over 272K tokens: $20.00 in, $75.00 out | OpenAI pricing Checked October 20, 2026 |
| GPT-6.1 Sol OpenAI | $2.00 | $0.10 | $10.00 | $2.50 (30 min) $5.00 (12 hr) | Over 272K tokens: $4.00 in, $15.00 out | OpenAI pricing Checked October 20, 2026 |
| GPT-6 Luna OpenAI | $0.10 | $0.01 | $0.50 | $0.125 (30 min) $0.25 (12 hr) | Over 272K tokens: $0.20 in, $0.75 out | OpenAI pricing Checked October 20, 2026 |
| Gemini 4 Argon Google Introductory price through November 30, 2026. From December 1, 2026: $4.00 input, $0.20 cached input, $20.00 output. | $2.00 | $0.10 | $10.00 | No separate charge | Same at any length | Google pricing Checked October 20, 2026 |
| Gemini 3.8 Flash Google Introductory price through December 31, 2026. From January 1, 2027: $1.50 input, $0.15 cached input, $7.50 output. | $0.75 | $0.075 | $3.75 | No separate charge | Same at any length | Google pricing Checked October 20, 2026 |
| Gemini 3.5 Flash-Lite Google | $0.30 | $0.03 | $2.50 | No separate charge | Same at any length | Google pricing Checked October 20, 2026 |
The CSV and JSON files carry every column, including cached and cache-write rates for long prompts.
Price change log
Tracking began with our check on October 8, 2026. When a monthly check finds a change, it gets a dated entry here and in the change log CSV. The date is the day of our check, so the vendor may have made the change on any day since the check before it.
- Google, Gemini 4 Argon: Google's new flagship model replaces Gemini 3.1 Pro Preview as its top model in this table, at an introductory $2.00 input and $10.00 output through November 30, 2026, then $4.00 and $20.00.
- Google, Gemini 3.1 Pro Preview: Replaced by Gemini 4 Argon as Google's top model. Google still lists it at $2.00 input and $12.00 output, or $4.00 and $18.00 for prompts over 200,000 tokens.
- OpenAI, GPT-6 Astra: OpenAI now lists a 12-hour cache write next to the 30-minute one: $25.00, against $12.50 for 30 minutes. Our October 8 check found one cache-write rate.
- OpenAI, GPT-6.1 Sol: 12-hour cache write listed at $5.00, against $2.50 for 30 minutes.
- OpenAI, GPT-6 Luna: 12-hour cache write listed at $0.25, against $0.125 for 30 minutes.
Embed the chart
The chart is rebuilt from the same table whenever a price changes, so an embedded copy stays current. Paste the HTML below where you want it. It loads the image from vantasoft.com and keeps the source line under it.
Embed code
<figure style="margin:0">
  <img src="https://www.vantasoft.com/resources/llm-prices-chart.svg" alt="Bar chart of standard API input and output prices per million tokens for current Claude, GPT and Gemini models" width="1200" height="860" style="max-width:100%;height:auto" loading="lazy">
  <figcaption>Source: <a href="https://www.vantasoft.com/resources/llm-prices">VantaSoft</a>, CC BY 4.0</figcaption>
</figure>
Reuse the data
The dataset is free to use under the Creative Commons Attribution 4.0 license (CC BY 4.0). You can copy it, chart it and publish it, including for commercial work. Credit VantaSoft and link to this page, for example:
Source: VantaSoft LLM API Price Dataset (https://www.vantasoft.com/resources/llm-prices), CC BY 4.0
The prices themselves are the vendors'. Check their pages before you sign a contract or set a budget on them.
How the data is collected
On the first of every month we read each vendor's official pricing page and update any price that changed. The table covers each vendor's current top, middle and small general text model. When a vendor replaces one, the new model takes its place and the change log records the swap.
The rates are standard pay-as-you-go API prices for text. Batch and flex processing, priority or fast modes, regional processing surcharges, cache storage and tools such as web search are priced separately and are not included.
Cached input is the price of reading a prompt back from the cache. Writing it to the cache costs more: Anthropic lists 5-minute and 1-hour writes, and OpenAI lists 30-minute and 12-hour writes. Google has no separate write charge, though its explicit caches pay hourly storage.
A token is not the same amount of text at every vendor. Anthropic says its Claude 4.7 and later models produce about 30% more tokens for the same text than its earlier models, so compare costs on your own prompts as well as on the price table.
Run the numbers for your workload
The LLM cost calculator runs these prices against your own workload, per request and per month. For weighing quality, speed and privacy alongside price, see which LLM to use for each kind of work.
Let’s talk aboutyour business.
We build custom AI agents, and we offer fractional CTO advisory and senior-level custom software development. It starts with a conversation.
Updated